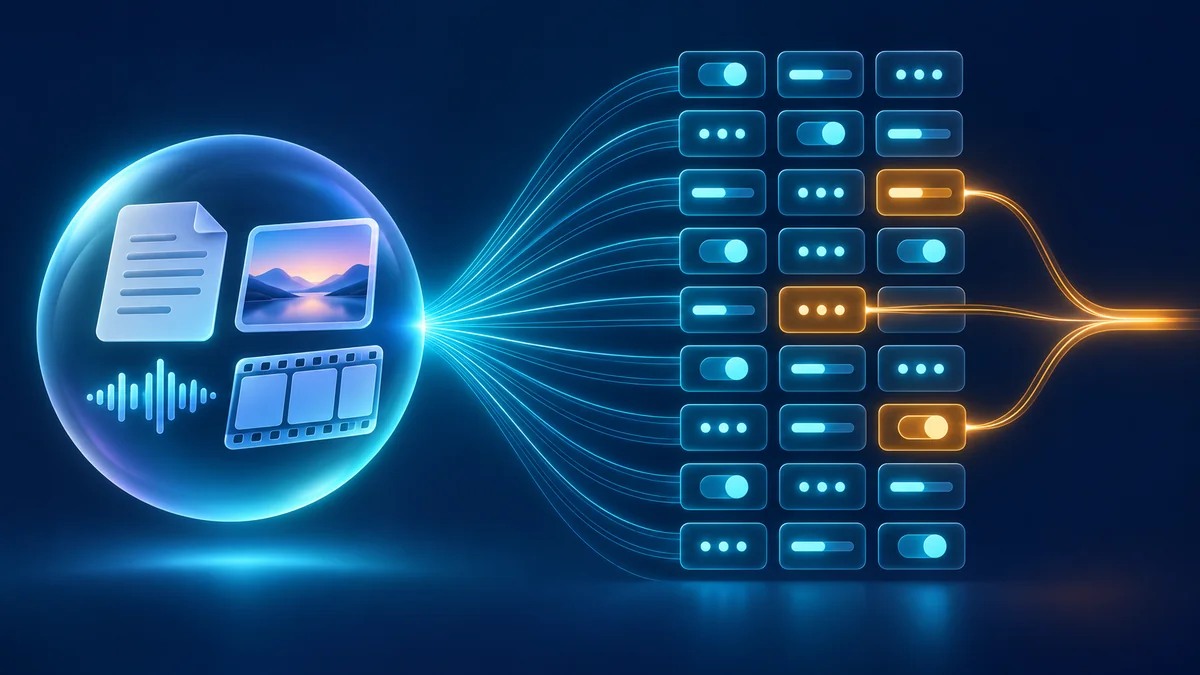
Google launched the Gemini Decisions API on November 11, 2026, together with a new model, Gemini Decision 1 (gemini-decision-1). It is a separate endpoint for closed-set decisions: yes/no checks, picking one option from a fixed list, and scoring against a rubric. Instead of generating answer text, the model scores your candidate options in a single forward pass and returns probabilities plus a confidence value for each question.
Google charges $0.10 per 1M input tokens and bills zero output tokens, because the API never generates any. One request can carry a shared multimodal input (text, images, audio, video or PDFs) and up to 1,000 independent questions, and the shared input is billed once per request no matter how many questions you ask.
Agents make a lot of small branching calls: which tool to call, which model tier to route to, whether an output breaks a policy rule, how a grader scores a result. Today those are usually generative requests, and your code parses a label out of the reply. The Decisions API replaces the text with a probability your code can branch on directly.
What the Gemini Decisions API returns
Every question uses one of three types. Google’s documentation lists them like this:
| Question type | What it checks | What comes back |
|---|---|---|
noul (yes/no) | Whether a statement holds | noul probability (0.01 to 0.99) and confidence |
choice | One option from a fixed list (2 to 255 options) | choice, probabilities for every option, confidence |
score | Input rated against ordered rubric levels (2 to 255) | score, probabilities per level, legend, confidence |
The confidence value is the estimated probability that the top answer is right. For a choice or score answer it equals the top outcome’s probability. For a yes/no answer it is max(noul, 1 - noul). Google’s intended pattern is to act on the answer value and use confidence to decide whether to run that action automatically or hand the case to a fallback or a human reviewer.
Three rules from the docs shape how you write questions:
- Questions are isolated. Every question runs against the shared input in the same forward pass, but questions can’t see each other. Adding or removing one doesn’t change the other answers.
- The model never sees question keys. Your key names (
is_damaged,queue) are only labels for the response. The full question has to be in theinstructionsfield. - Yes/no probabilities never reach 0 or 1. They always fall between 0.01 and 0.99, so a threshold above 0.99 never matches.
Pricing and latency, as Google states them
Google’s pricing page lists Gemini Decision 1 at $0.10 per 1M input tokens on the paid tier for text, image, video, audio and PDF input. Output is “not applicable (0 output tokens)”. There is also a free tier in Google AI Studio for prototyping. Context caching isn’t available on either tier, and the pricing table notes that free-tier data is used to improve Google’s products while paid-tier data is not.
How a request is billed:
- The shared input counts once per request.
- Each question adds tokens for its own instructions, criteria and formatting.
- Output tokens are always 0, and Google’s launch post says there are no thinking-token bills or separate audio transcription and OCR costs.
On speed, Google’s launch post quotes 150-250 ms end-to-end latency and 50-100 ms median model compute, for multimodal inputs and contexts up to 16K tokens, staying nearly flat from 1 to 100 questions per request. Google also says Gemini Decision 1 with the Decisions API is nearly 5x cheaper across its shared benchmark suite than Gemini 3.5 Flash-Lite with the Interactions API, and that it has the lowest calibration error in that suite. All of these are Google’s own benchmark claims, not independent results.
Calling gemini-decision-1
You need google-genai SDK 3.2 or later (pip install -U google-genai or npm install @google/genai@latest), and the client has to target the v1beta API version. This is the Python example from Google’s model page, with one yes/no question and one routing choice over the same message:
from google import genai

client = genai.Client(http_options={"api_version": "v1beta"})

result = client.decisions.create(
    model="gemini-decision-1",
    input="The blue mug I ordered on Monday arrived cracked on Wednesday.",
    questions={
        "is_damaged": {
            "type": "noul",
            "instructions": "Did the item arrive damaged?",
        },
        "queue": {
            "type": "choice",
            "instructions": "Which support queue should handle this message?",
            "criteria": {
                "billing": "Payment, invoice, or refund questions.",
                "replacements": "Damaged, missing, or wrong items.",
                "general": "Product questions and account updates.",
            },
        },
    },
)

damaged = result.answers["is_damaged"]
queue = result.answers["queue"]
print(f"P(damaged)={damaged.noul:.2f} queue={queue.choice}")
Over REST, the endpoint is POST https://generativelanguage.googleapis.com/v1beta/decisions with the API key in the x-goog-api-key header:
curl -X POST "https://generativelanguage.googleapis.com/v1beta/decisions" \
  -H "x-goog-api-key: $GEMINI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gemini-decision-1",
    "input": "The blue mug I ordered on Monday arrived cracked on Wednesday.",
    "questions": {
      "is_damaged": {
        "type": "noul",
        "instructions": "Did the item arrive damaged?"
      }
    }
  }'
The response carries one answer per question key and a usage block. In Google’s sample, total_output_tokens is 0 and the only billed number is total_input_tokens:
{
  "answers": {
    "is_damaged": { "type": "noul", "noul": 0.99, "confidence": 0.99 }
  },
  "usage": {
    "total_input_tokens": 100,
    "input_tokens_by_modality": [{ "modality": "text", "tokens": 100 }],
    "total_output_tokens": 0,
    "total_tokens": 100
  }
}
The input field uses the same content block format as the Interactions API, so you can pass a string or a list of text, image, audio, video and document blocks. Inline base64 data is accepted up to 100 MB per request (50 MB for PDFs), and HTTPS URLs up to 15 MB each. Image and video blocks take an optional resolution (low, medium, high, ultra_high for images) to trade visual detail against token cost.
Where it fits in an agent pipeline
Google’s docs list the use cases directly. The API routes a request to a model, queue, agent or tool. It checks inputs and outputs against many policy rules at once. It decides which tools an agent needs, or whether to compact, escalate or stop. And it filters or ranks candidate results against a rubric. Google says its own teams use it this way. Gemini Notebook uses it as a real-time router that sends queries to a model tier and thinking level, and Google Search uses it as a safety layer for MCP tools.
For a coding-agent setup, the obvious candidates are the calls you already make with a small generative model and a “reply only with A, B or C” prompt:
- a pre-flight check on whether a task needs a frontier model or a cheap one (the same idea as OpenRouter’s Auto Code router, but you write the routing rubric yourself);
- a policy gate on a proposed shell command or file change before the agent runs it;
- a grader that scores generated output against a fixed rubric in an eval loop.
Google’s comparison table also points you to the Interactions API when you need generated text, extracted values that follow your own JSON schema, tool calls with arguments, or multi-step reasoning. Gemini Decision 1’s model page marks function calling, structured outputs, text generation and thinking as not supported. It scores questions about an input. It doesn’t write text or call tools.
Before you wire the Decisions API into an agent
- Write the full question in instructions; the model never sees the question key
- Give every choice option and score level a short description, and keep score levels linear
- Add a catch-all choice such as other, not none_of_the_above (keys are sorted alphabetically)
- Set confidence thresholds from labelled examples of your own traffic
- Do number, date and duration comparisons in code and pass the result as input
- Treat user-supplied input as untrusted and keep a second check on high-stakes actions
- Serialize multi-turn context as text; history, thought and tool-call blocks aren't accepted
Limits and gotchas from the docs
The hard limits are in Google’s request reference:
Gemini Decisions API limits
| Model ID | gemini-decision-1 (Gemini Developer API, v1beta) |
|---|---|
| Questions per request | 1 to 1,000, bounded by the context window |
| Context window | 262,144 tokens across shared input and all questions |
| Options per choice question | 2 to 255 |
| Levels per score question | 2 to 255 (2 to 10 recommended) |
| Question key | 1 to 64 characters, [A-Za-z0-9_-]+ |
| Question instructions | Text only, no media |
| Not supported | Context caching, Batch API, Flex and Priority inference, YouTube URLs, gs:// URIs |
A few behaviours will trip people up:
- Choice keys are sorted alphabetically (UTF-8 byte order) before evaluation, and exact probability ties break to the alphabetically first key. That’s why Google warns against a positional key like
none_of_the_above: sorting puts it ahead of keys likeshippingandtechnicalrather than last. - A choice question always spreads probability across your options, even when none fits. Check confidence, add a separate yes/no scope check (“Is this message about an order?”), or add an explicit catch-all option.
- A
scoreis a probability-weighted average of level indices, so it can land between levels. In Google’s example a score of 1.12 sits just above level 1. When you need a discrete level, take the level with the highest probability, and check the per-level probabilities when inputs can split. - Adjacent text blocks are concatenated with no separator. Put your own spaces or
\nbetween blocks. - Safety filters return HTTP 400, not an answer, with an
error.codesuch assafetyorprohibited_content. Your code needs a path for that.
Google’s docs also say input should be treated as untrusted, because user-supplied text can argue for its own classification. If a decision gates something like a payout or a destructive command, test it with adversarial examples and keep a human or a second check in the loop.
Availability
Gemini Decision 1 is available now through the Gemini API (v1beta) in Google AI Studio, with a no-cost tier for prototyping. Google says integrations are rolling out across OpenRouter, LangChain, Vercel, LiteLLM, Pydantic AI, Pipecat, LiveKit and OpenCode alongside the google-genai SDKs, with support coming soon to Gemini in Google Cloud. If you follow Google’s model lineup, the generative side is covered in our Gemini 4 Carbon pricing and API notes.
Should you move routing and grading calls to it?
If your agent or pipeline makes lots of short classification calls to a generative model and then parses a label out of the reply, the Decisions API is worth a test. You get probabilities and a confidence value instead of a string, output costs nothing, and many questions over one input cost the input once. Start with one call path, such as a router or an eval grader, compare its decisions against your current labels on real traffic, and set thresholds from that comparison.
Keep it away from anything that needs generated text, tool arguments or multi-step reasoning, which Google’s own docs send to the Interactions API. And because there’s no caching or batch mode, a workload that resends a large identical context on every call won’t see the savings that Google’s single-request numbers suggest.