Edge0 open-sourced two large local models on November 12, 2026: Edge0-145B and Edge0-120B. Edge0’s launch post calls Edge0-145B the first open-source on-device model with 145 billion parameters, and reports 29GB peak memory, 1,100+ tokens/s prefill and 80+ tokens/s decode on a compatible laptop. The weights are on Hugging Face, and the GitHub release v0.2.0 ships a new local inference engine, edge0-infer, with OpenAI-compatible and Anthropic Messages endpoints.
The project README adds two details the launch post leaves out. The 145B and 120B models are “derived from Qwen3.8-Flash-Next and trained natively at 4 bits”, and the current build runs them only on Linux or Windows with an NVIDIA GPU and CUDA 13. macOS isn’t on that list yet, even though the launch post talks about day-one macOS support.
Every benchmark and speed figure here comes from Edge0. Edge0 says the full evaluation setup and a technical report are still to come, so treat the numbers as vendor claims until someone reproduces them.
How Edge0-145B fits a 145B model into 29GB
Edge0’s launch post describes four design choices that work together:
- Shared expert matrices. Each group of 64 experts shares two large matrices, and each expert keeps a small set of its own parameters. Only about 10B of the 145B parameters take part in each inference step.
- Training in the on-device shape. Edge0 says it trained the model in its local architecture from the start, instead of compressing a cloud model after training.
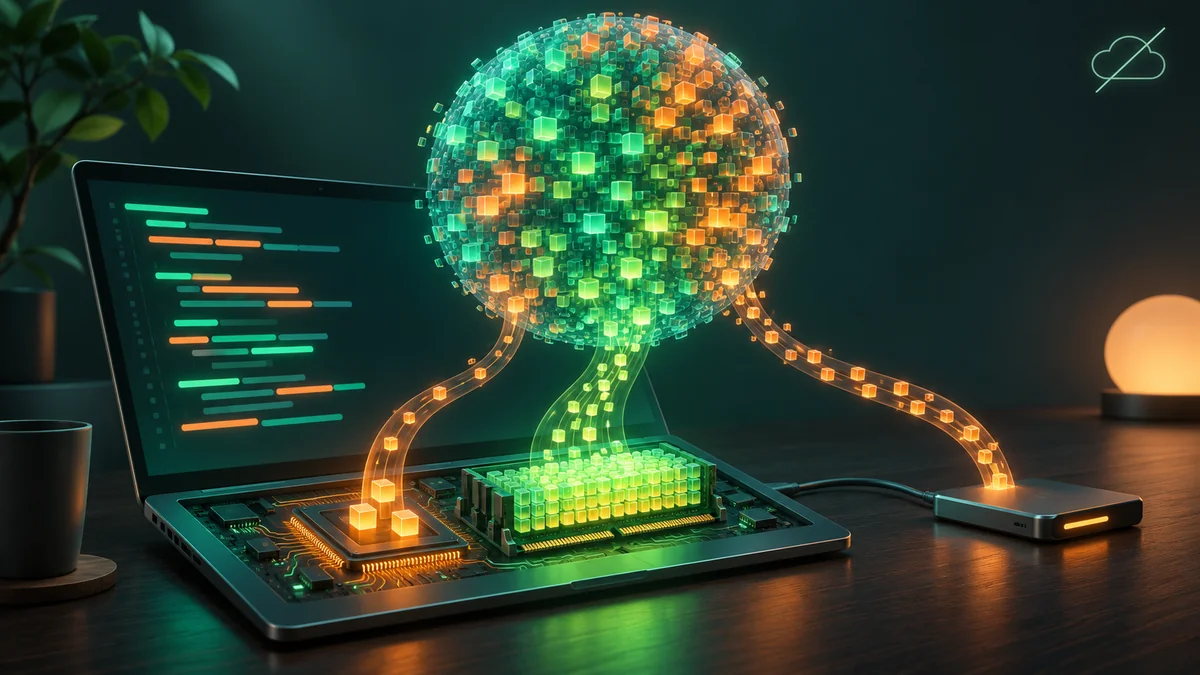
- Three storage tiers. Frequently used “hot experts” stay in GPU memory. An expert library of about 40GB sits in system memory and moves to the GPU as needed. About 48GB of vocabulary data stays on the SSD and is read on demand.
- CPU and GPU together. The GPU computes cached experts while the CPU handles the rest in parallel, and speculative decoding checks several candidate tokens at once, which spreads the cost of reading weights over more output tokens.
The README describes the routing in more detail: both models use latent MoE, route each token to 10 of 512 experts plus one shared expert, and have 48 layers. The 145B model uses latent width 1792 and the 120B model uses 1280.
The SSD tier is what makes the memory figure possible, and it’s also why your drive matters. Weights that live on the SSD have to be read during generation, so a slow disk shows up as slower output.
Hardware and platform support
The v0.2.0 release notes and the README agree on what runs today:
Edge0-145B and Edge0-120B requirements (v0.2.0)
| Engine | edge0-strata (a fork of Strata), started by edge0-infer serve or edge0-infer chat |
|---|---|
| Operating system | Linux or Windows; release packages for v0.2.0 are Windows only |
| GPU (x64) | NVIDIA, compute capability 7.5 or newer (RTX 20/30/40/50), at least 16 GiB GPU memory |
| GPU (Windows Arm64) | NVIDIA compute capability 12.1, such as RTX Spark N1X; CUDA code built for sm_121 only |
| System memory | At least 20 GiB |
| Software | NVIDIA CUDA Toolkit 13 |
| Weights | Not in the packages; download Q3_K or NVFP4 builds from Hugging Face |
The README also says the 16 GiB VRAM plus 20 GiB RAM budget in its tables “is a test limit, not a minimum system requirement”. Those rows are an RTX 5090 D 24 GB card held to that budget with cgroup limits, not a separate 16GB card.
What Edge0 reports for speed and quality
The README lists Edge0-145B speeds by machine and weight build. A few rows, in tokens per second:
| Machine | Build | 16K prefill | Agent decode |
|---|---|---|---|
| RTX 5090 D 24 GB | Q3_K | 3554.9 | 121.2 |
| RTX 5090 D 24 GB | NVFP4 | 3165.7 | 98.3 |
| RTX 4090 24 GB | Q3_K | 3179.4 | 91.7 |
| RTX Spark N1X 60 GiB | NVFP4 | 922.4 | 46.0 |
| 16 GiB VRAM + 20 GiB RAM budget | Q3_K | 335 | 44.9 |
At full residency on the RTX 5090 D, the README says the Q3_K build (40.81 GiB of weights) sits as 23.14 GiB in VRAM and 31.28 GiB in RAM. Those are the README’s figures for that card, and they’re higher than the 29GB peak in the launch post, so check which build and budget a number refers to before you size a machine.
On quality, Edge0’s launch post reports these results from its own evaluations:
| Model | DeepSWE 1.1 | Terminal-Bench 2.1 | GPQA-Diamond | IFBench |
|---|---|---|---|---|
| Edge0-145B | 64.6 | 86.52 | 90.4 | 80.6 |
| Edge0-120B | 53.6 | 81.3 | 87.4 | 79.3 |
| Qwen3.8-Flash-Next | 58.7 | 83.3 | 91.7 | 81.3 |
| DeepSeek-V4-Flash-0731 | 54.4 | 82.7 | 90.8 | 79.2 |
Edge0 puts Edge0-145B’s mean across six benchmarks at 72.8 with 29GB measured peak memory, against 71.7 for Qwen3.8-Flash-Next, which Edge0 estimates at about 70GB for a standard 4-bit deployment. Edge0 marks that 70GB as an estimate still to be measured. Since the README says Edge0-145B is derived from Qwen3.8-Flash-Next, this comparison mostly measures how much of the base model’s quality Edge0’s conversion keeps at a smaller memory footprint. Edge0’s own table has the 145B model ahead on DeepSWE 1.1 and Terminal-Bench 2.1 and slightly behind on GPQA-Diamond and IFBench.
Running it as a local endpoint for coding tools
The README’s quick start builds two parts from the repository, edge0-strata and edge0-infer, then serves a single model folder. Pass the folder for one model (for example Edge0-145B-q3k), not a folder that holds several:
git clone https://github.com/Edge0-AI/Edge0.git edge0
# build edge0-strata and edge0-infer per edge0-strata/EDGE0.md and edge0-infer/docs/getting-started.md
build/cpu/bin/edge0-infer serve --model /path/to/Edge0-145B-q3k
On Windows the program is build\windows\bin\edge0-infer.exe. Once the weights load, the README says it prints Listening: http://127.0.0.1:8000 model=<name>, where the name is edge0_145b, and serves OpenAI- and Anthropic-compatible endpoints. The README’s test call:
curl localhost:8000/v1/chat/completions -H 'content-type: application/json' -d '{"model":"edge0_145b","messages":[{"role":"user","content":"hi"}],"max_tokens":64}'The v0.2.0 release notes say the server also answers POST /v1/messages and POST /v1/messages/count_tokens, and that LAN authentication accepts x-api-key. That Anthropic Messages support is what lets tools built for Anthropic’s API talk to a local model. We covered how that wiring works in Anthropic-compatible endpoints for Claude Code. For the 145B and 120B models, use serve or chat; the README says run belongs to the older native engine.
If you download the Windows release package instead of building, the release notes publish a SHA256 for each zip. On Windows, PowerShell can check the x64 package:
Get-FileHash .\edge0-chat-0.2.0-windows-x64.zip -Algorithm SHA256
# expected: c7146b76d51c7986723b81a3643893e1ccbb09ce4f365a5090dc99e476bb31b9
Licenses: code and weights differ
The GitHub repository is Apache-2.0, and the README says the framework code stays under Apache-2.0. The model weights are a different case. The Hugging Face model card tags the weights as license “other”, named edge0-community-model-1.0, and lists Qwen/Qwen3.8-Flash-Next as the base model, with a Qwen license file in the repo’s third-party folder.
Before you use Edge0-145B at work
- Read the Edge0 Community Model License 1.0 as well as the Apache-2.0 code license
- Get Edge0's written permission before selling the model, paid distribution, or running a paid inference or fine-tuning service
- Check the upstream Qwen license terms that the Edge0 license says still apply
- Confirm your GPU meets compute capability 7.5+ with 16 GiB VRAM, plus 20 GiB RAM and CUDA Toolkit 13
- Treat the benchmark and memory figures as Edge0's own until the technical report is out
The README says the model license permits personal use, research, education, modification, noncommercial sharing, internal use and commercial use of generated outputs. It needs separate written permission from Edge0 for model sales and paid distribution, and for commercial model services that offer inference or fine-tuning.
Is Edge0-145B worth trying?
If you have a recent NVIDIA card with 16GB or more of VRAM on Linux or Windows, yes, as a local endpoint you can point an agent at without per-token fees or sending code off the machine. Start with the Q3_K build, which the README’s tables show as the faster of the two on the RTX 5090 D and RTX 4090, and measure decode speed on your own disk and memory before you rely on it. Local inference still costs hardware and electricity, as Edge0’s own post points out.
If you’re on a Mac, the current release doesn’t cover these models, despite the launch post’s macOS claim. And if you plan to offer it as a service, read the model license first, because the Apache-2.0 badge on the repo doesn’t cover the weights. For other local coding setups, see our OpenClaw with Ollama guide.